The first time I let the robot arm run on its own, it worked! It reached down, grabbed the sock, lifted it, and dropped it into the cardboard box. No joystick, no me, just a model I'd trained on my laptop. It was like magic. My wife and I genuinely cheered 😄
Then I ran it again. And it failed, again and again 😅 Only 2 of the first 10 runs succeeded.
This is the story of training my first policy (the AI model that decides how the robot moves) for the SO-101 arm: real commands, real numbers, the mistakes I made and what they taught me.
Learning to drive an arm
Before a robot can learn from you, you have to be worth learning from. In imitation learning you teach by demonstration, and demonstrating means teleoperating: you move the leader arm by hand, the follower arm mirrors you, and the system records everything.
But teleoperation is a skill. The first sessions were genuinely clumsy: the movements didn't feel natural, and completing the task at all was hard. I failed plenty: the sock fell outside the box; the sock bounced off the rim and landed outside; and more than once the drop hit the box's edge and flipped the whole container 90 degrees, because a cardboard box weighs nothing.
Then, slowly, the robot arm became something like part of my body. As I kept trying, precision arrived, the failures became rare, and I could do the task smoothly. That's the version of me the robot got to learn from. All in all, it took me about 10–15 minutes to get used to teleoperating the arm.
Recording 54 episodes
A demonstration in robotics is called an episode: one complete run of the task, captured as data: both camera streams (the gripper's view and an external view) plus the positions of all six motors, frame by frame. I recorded 54 episodes in one sitting of about two hours, with tiny breaks to rest, deliberately moving the sock and the box around between episodes (sock left and box right, then reversed, then everything in the middle) so the model wouldn't just memorize one layout or movement.
Recording runs through LeRobot's command-line tool. This is the command I used to record the demonstrations:
lerobot-record \
  --robot.type=so101_follower \
  --robot.port=/dev/tty.usbmodem<follower> \
  --robot.cameras="{ front: {type: opencv, index_or_path: 0, width: 1920, height: 1080, fps: 30}, wrist: {type: opencv, index_or_path: 1, width: 1920, height: 1080, fps: 30}}" \
  --teleop.type=so101_leader \
  --teleop.port=/dev/tty.usbmodem<leader> \
  --dataset.repo_id=${HF_USER}/so101-sock-in-box \
  --dataset.num_episodes=54 \
  --dataset.single_task="Grab the sock and put it in the box"
Episodes record at 30 fps by default. The dataset uploads to the Hugging Face Hub as you go, which turned out to be very useful: the demonstrations become a portable dataset I can later use on any machine, for example to train a bigger, smarter policy on cloud GPUs.
Training on a laptop
I then trained an ACT (Action Chunking Transformer) model on my MacBook Pro M3 using these 54 episodes. ACT is a policy well suited to robot control because it predicts short chunks of movement at a time instead of twitching one step at a time.
The command to train the policy in LeRobot is quite straightforward:
lerobot-train \
  --dataset.repo_id=${HF_USER}/so101-sock-in-box \
  --policy.type=act \
  --policy.device=mps \
  --steps=100000 \
  --batch_size=8 \
  --save_freq=5000 \
  --wandb.enable=true \
  --output_dir=outputs/train/act_sock_in_box
Let's unpack what's in this command:
--policy.device=mpstells PyTorch to use the MacBook's Apple Silicon GPU through MPS (Metal Performance Shaders) instead of an NVIDIA GPU.- A step is one round of the model studying a batch of slices from your episodes, guessing the next movements, checking how wrong it was, and adjusting.
- A batch is how many of those slices it studies per step: 8 here, LeRobot's default, inherited from the original ACT paper.
- A checkpoint is a saved snapshot of the model mid-training; I saved one every 5,000 steps.
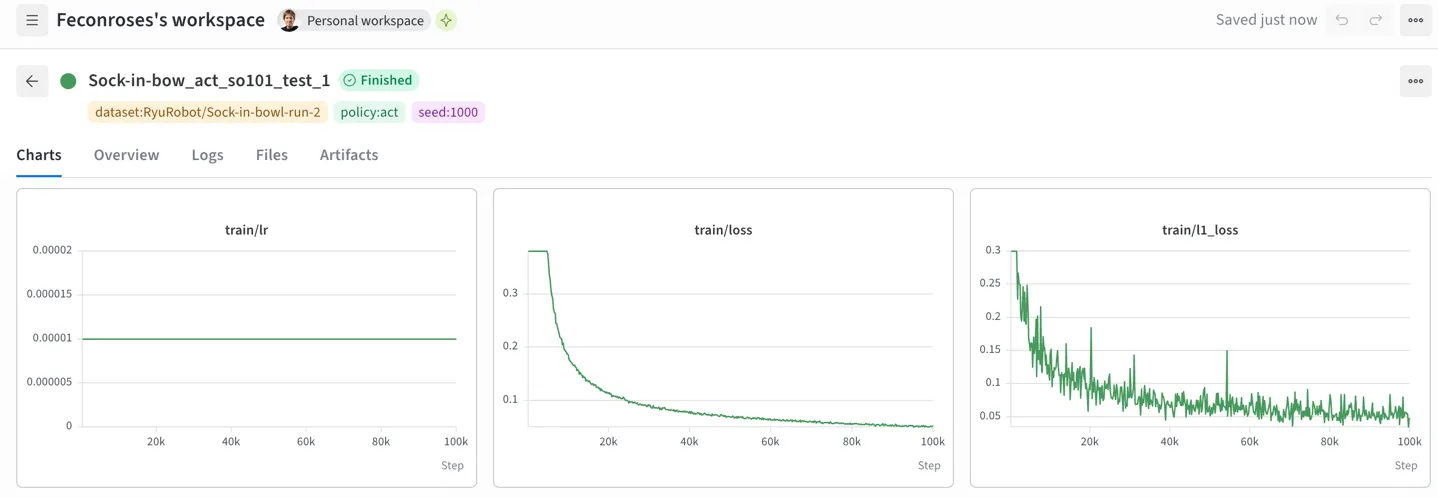
On my MacBook Pro M3, 100,000 steps took around 23–24 hours. I let it run overnight and through the next day, watching from my phone via Weights & Biases, a free service that charts your training as it runs. That's worth setting up on day one: it shows you the loss (how wrong the model currently is) trending down, and when you train more than once, it lets you compare runs against each other instead of against your memory.
The first run, and the second
The first autonomous run of my freshly trained ACT policy went GREAT! One clean grab, one clean drop, two adults cheering at a robot arm in their living room 😂
Reality checked in on the runs after that. The arm struggled: missed grasps, half-grabs where the sock slipped away, approaches that stalled:
The first success turned out to be closer to a good roll of the dice than a solved task.
I had a few hypotheses for the low success rate:
- Not enough data. 54 episodes is very little training data.
- Position coverage. I suspected the failures clustered where the sock or box sat in spots my episodes had barely covered.
- Lighting drift. I recorded in the living room at different times of day, with no lighting gear; the model may have been fighting shifting shadows.
- Frame rate. Episodes were recorded at 30 fps; whether my MacBook could actually sustain that rate at inference time is a good question I hadn't measured, and it could affect performance.
25 more episodes
I tested the one hypothesis I could act on cheaply: coverage. I recorded about 25 more episodes, aimed specifically at the under-represented sock and box positions, and retrained from scratch on the full 79-episode dataset: same recipe, 100,000 steps, another day of laptop fans.
The new policy, trained on all 79 episodes, was slightly better: roughly 3 successes in 10 attempts. But it still struggled a lot. More data had helped, but it clearly wasn't the whole story, and that's when the actual lesson finally landed.
The real lesson: I chose a bad first task
It's not that ACT sucked. It's that I picked a bad first task for it.
Look at what I actually asked for:
- The sock is malleable, squishy, and featherweight: it deforms in the gripper, slides through half-closed jaws, and moves if the gripper so much as brushes it in passing.
- The cardboard box weighs nothing and shifts or flips when a drop lands on its edge. Remember the container doing a 90-degree flip back in my teleop practice? The physical properties of my objects were quietly part of the machine learning problem the whole time, and I'd picked two of the least cooperative objects in the apartment 😅
A rigid object (say, a wooden die) and a heavier, solid container would have made a world of difference: consistent grasps, a target that stays where you put it, failures that mean something.
What I learned
- Your objects are part of your ML problem. Squishiness, weight, and friction are features the model has to cope with. Before asking "which policy?", ask whether the task fits the training data, compute and policy you plan to use. If you're just getting started, pick a simple task the policy can learn easily.
- The first success is not a solved task. One clean run tells you the pipeline works, not that the policy does. Run it twenty times before you celebrate.
- A good session is not a metric. I wasn't logging trials properly, so every conclusion was vibes. Log attempts and outcomes from day one.
- Checkpoints are cheap insurance. A 24-hour run on a laptop will test your faith; save a snapshot every 5k steps so a crash at hour 20 doesn't mean starting over. Checkpoints also let you test later whether the final model was actually the best one (sometimes it isn't!).
- Run tracking is fun and useful. A live loss curve shows your progress during a 24-hour run, and it's exciting to watch the model improve as training goes on.
What's next
The 79 episodes aren't done working. I've already fine-tuned π0.5, a newer, smarter, much bigger open-source policy, on that same dataset, using a rented cloud GPU because my laptop wasn't enough for that one. Whether a smarter model can rescue my badly designed task with the same data is exactly the kind of question the next post gets to answer.
After that, I want to run a new experiment: a second, deliberately simple task (rigid object, stable target) to give ACT the fair test I didn't give it the first time.
If you had this arm on your desk, what would you teach it first? And if you have ideas for improving this ACT policy, please leave a comment. I'd genuinely love to hear them.
Comments
Loading comments…